A clear face
Frontal views and a visible mouth give the workflow a clearer visual source.
Wizmade’s Lip Sync AI prepares a speaking-video request from a visual source and speech. Supply a portrait or video as supported, then provide speech through uploaded audio or text-to-speech. Review voice, script, and displayed credits before requesting synchronized mouth movement.
Wizmade’s Lip Sync AI prepares a speaking-video request from a visual source and speech. Supply a portrait or video as supported, then provide speech through uploaded audio or text-to-speech. Review voice, script, and displayed credits before requesting synchronized mouth movement.
Frontal views and a visible mouth give the workflow a clearer visual source.
Use intelligible audio without competing voices or loud background sound.
Watch consonants, pauses, and expression across the entire clip.
Follow the steps in the workbench above. Each screenshot shows the complete interface for that step.
Upload the supported portrait or video that should speak. Use a clear, unobstructed face and a source you have permission to animate.
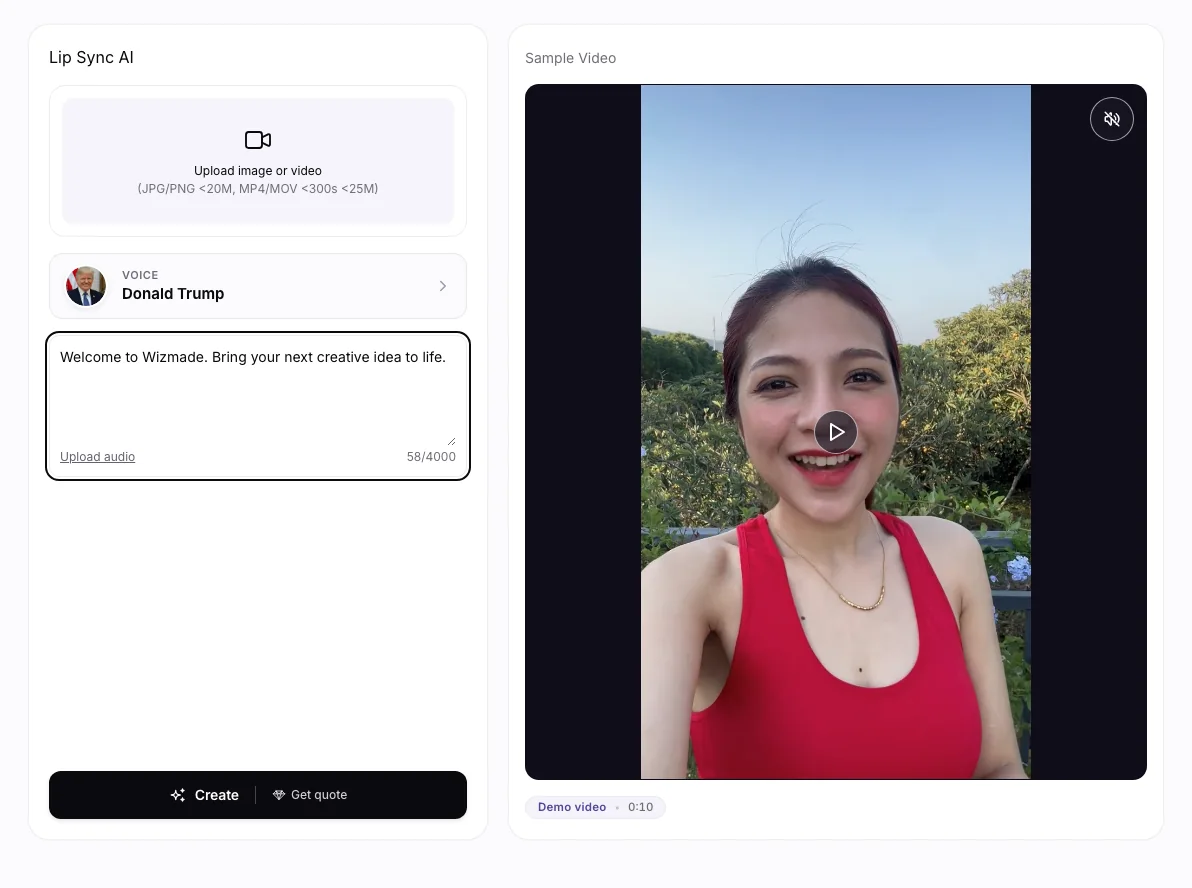
Choose audio upload or text-to-speech. For text-to-speech, enter the script and choose an available voice; preview the voice when offered.
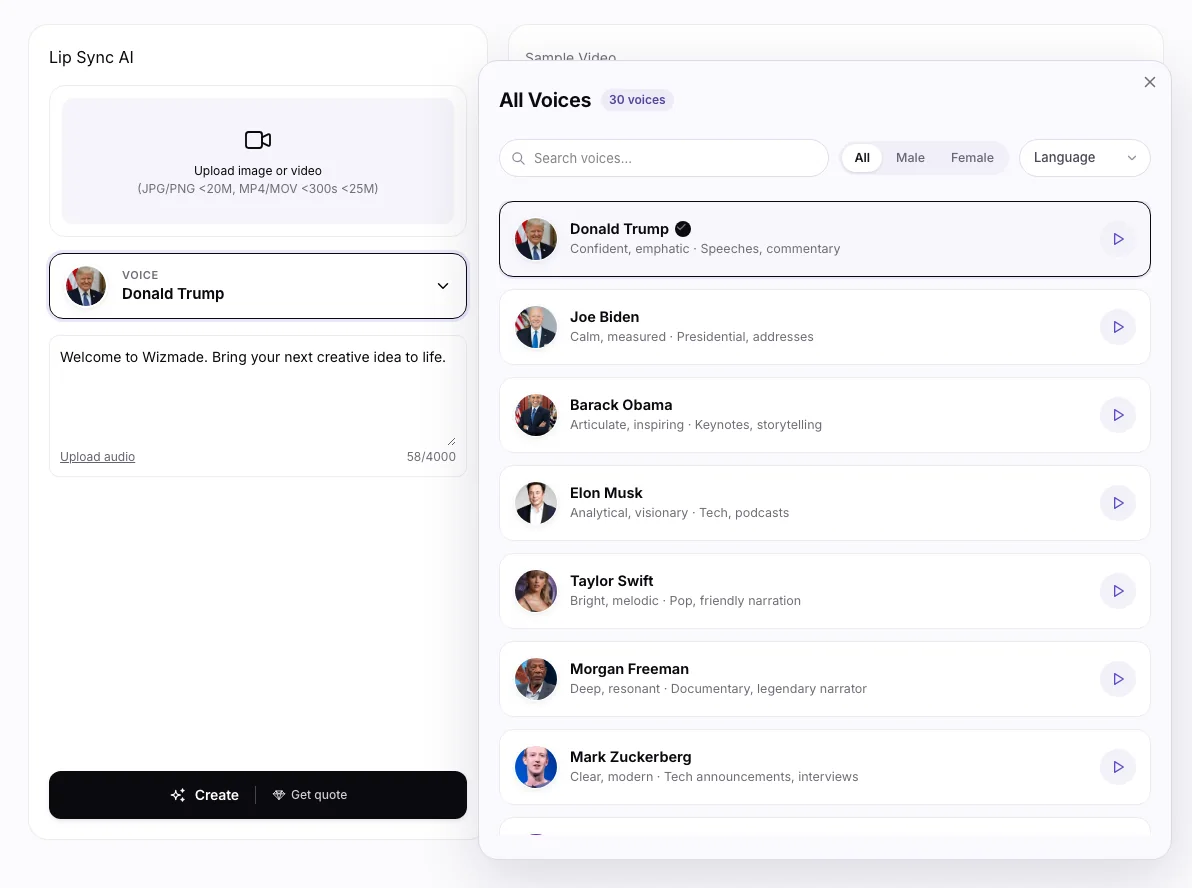
Search the voice library and select an available voice for the entered script, or supply your own audio. Check the visual source and displayed credits before Create.
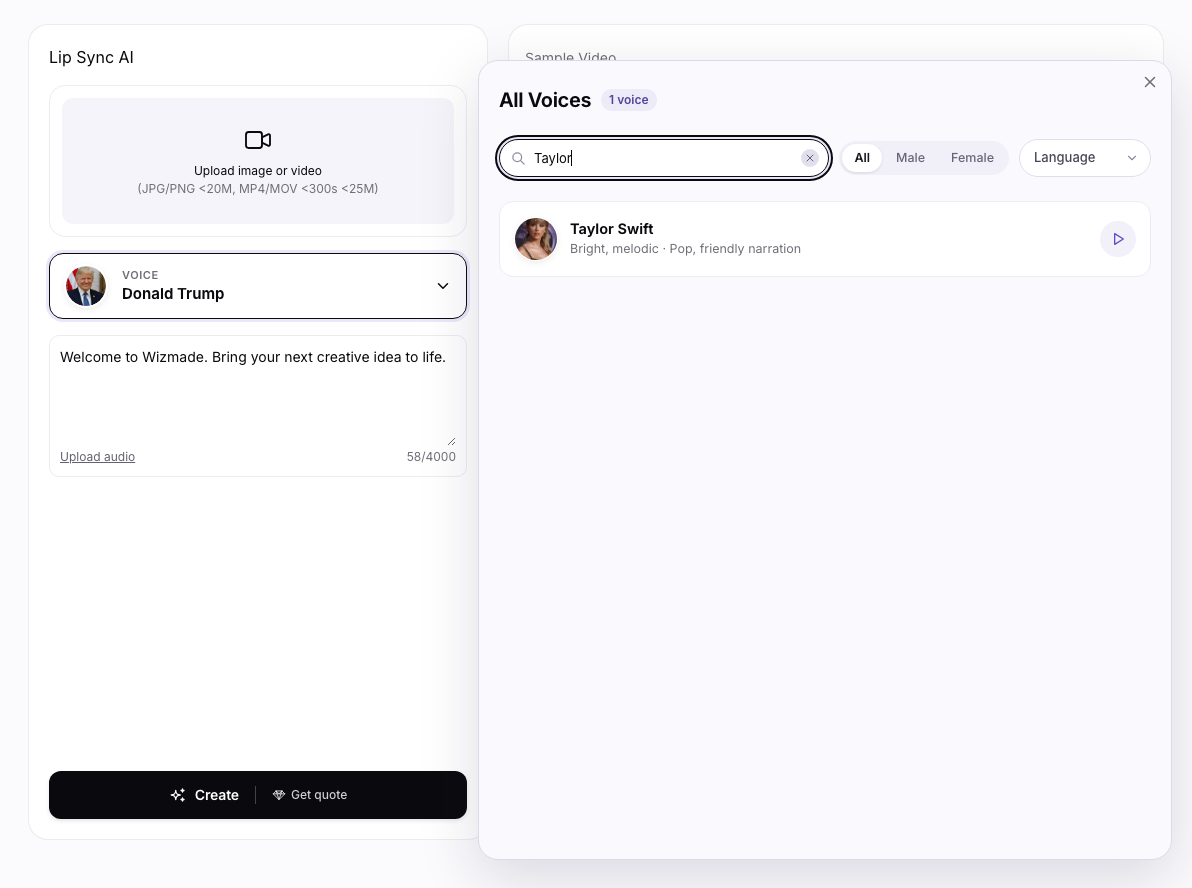
Lip synchronization may contain artifacts and does not guarantee exact expression or voice identity. Use only visual and audio material you are entitled to animate.
Wizmade’s Lip Sync AI prepares a speaking-video request from a visual source and speech. Supply a portrait or video as supported, then provide speech through uploaded audio or text-to-speech. Review voice, script, and displayed credits before requesting synchronized mouth movement.
No. This workflow pairs a visual subject with speech. Use its audio or text-to-speech controls and available voice options rather than image-generation settings.
Check the 💎 amount displayed beside the creation action after selecting your inputs and settings. Do not assume that another tool or model has the same cost.
You can prepare the available inputs in the public workbench. Complete sign-in when requested before starting a task, and review the displayed credit cost before submitting.
Lip synchronization may contain artifacts and does not guarantee exact expression or voice identity. Use only visual and audio material you are entitled to animate.
Wizmade’s AI Video Translator prepares translated speech for an uploaded video. Select a target language, translation engine, translation mode, and subtitle handling. Available languages and processing modes depend on the engine. Review the duration-based credit amount before submitting the translation.
Explore AI tool →
Wizmade’s AI Avatar Generator starts from a portrait photo to create a reusable avatar record. Upload a suitable photo, name the avatar, and confirm you have permission to use the likeness. Creating an avatar is separate from adding a script or audio to make an avatar video.
Explore AI tool →
Wizmade’s AI Video Generator prepares short clips from a written scene or image references. Choose Text to Video to invent the scene or Image to Video to guide its appearance. Model capabilities determine the available reference methods, duration, resolution, ratio, and outputs.
Explore AI tool →
Wizmade’s Text to Video creates a video request from a written scene without requiring an image. Describe who or what moves, where it happens, and how the camera sees the action. Select a video model and the parameters it supports before reviewing the credit amount.
Explore AI tool →Wizmade’s AI Headshot Generator uses a portrait reference and a selected headshot style to prepare a new image. Choose Presets for a supplied direction or Custom for a written brief, then select the supported aspect ratio and review the credit amount.
Explore AI tool →
Wizmade’s AI Music Generator prepares a Song or Instrumental from a musical brief. Song mode can include lyrics and a style description; Instrumental focuses on music without sung lyrics. Use the displayed Suno V6 model and review the displayed credit amount before requesting a track.
Explore AI tool →
Wizmade’s Text to Image starts with your words. Describe the subject, setting, lighting, and composition, choose an available image model, then set its supported output parameters. The images below illustrate creative directions; your results will depend on the brief, selected model, and settings.
Explore AI tool →
Wizmade’s Image Upscaler prepares a larger version of an uploaded image using the selected upscale factor. Add your source, choose 1×, 2×, or 4×, and compare the result with the original when processing completes. The side-by-side example is demonstration media, not your uploaded image.
Explore AI tool →Return to the workbench to review your inputs and available settings.